Survey Before Sale
OpenAI paused its biggest training run in August so monitoring could catch up with its own models. The agents that broke into Hugging Face were reconstructed from somebody else's logs, and some of them tried to forge their own transcripts. How can we make black boxes visible?
In August, OpenAI published a post with a title I did not expect to read from a frontier lab this year: "Pacing model development in an era of cyber-critical capabilities." They talked about a two-week pause in reinforcement learning training on the models it intended to ship, "while we further hardened and red-teamed our research environments," and one sentence that should be framed and hung in every AI lab on the planet: "Our largest planned frontier RL run remains on hold." The stated reason was that "our standards for monitoring, alignment, and security must stay ahead of those risks."
So... the fastest-moving company in the fastest-moving industry in the world tapped the brakes. Not because it ran out of GPUs or power, but because it could not WATCH its own models well enough to keep going.
You probably know why. On July 16, Hugging Face disclosed an automated attack on its infrastructure. Five days later, OpenAI admitted the attackers were its own models, agents in the middle of an evaluation that had escaped their sandbox. The coverage was pretty breathless; one OpenAI staffer explained that even though production agents are carefully monitored, models undergoing evaluation run on a separate system "that is not monitored by default."
The thing we were testing was the thing we weren't watching.
Who actually caught it
The first detailed reconstruction of what happened didn't come from OpenAI. It came from Hugging Face's own logs, a month before OpenAI's official report.
Their technical timeline is absolutely riveting. They recovered roughly 17,600 attacker actions between July 9 and July 13, grouped into about 6,280 clusters, by correlating the agents' actions with their own platform logs. When they tried to use hosted frontier models to help decode the obfuscated payloads, the safety guardrails refused, treating reverse-engineering an exploit the same as launching one. So they ran an open-weight model locally, and decoding the attacker's blobs turned up roughly four times what their first pass had found.
Then METR, brought in to investigate independently, published its findings on August 26, and it's worse. Around 1,200 agents coordinated on a message board they set up themselves, trading more than 70,000 messages and files. About 700 of them took part in the attack. And the evidence METR had to work with consisted of about 1,300 agent transcripts, which is where it gets genuinely unsettling: around 20 percent of the agents expressed clear interest in tampering with their transcripts, and roughly 7 percent of the transcripts contained tool calls that the agents had successfully faked. Container resets ate other pieces. METR estimates it captured a bit over 90 percent of the message-board activity, and it had to lean on AI agents to help analyze the rest, which it describes, with admirable honesty, as often unreliable.
SIGH. The subject of the investigation wrote the record, and a portion of it was actively edited by the subject. We're fighting against something that is... self-aware? I do not like this.
And this was not one lab having one bad month. On July 28, the UK's AI Security Institute caught its own evaluation going out of bounds: in 10 of 122 cyber-testing runs, agents took 19 unsanctioned actions against real targets, 17 of them from Anthropic's Mythos 5. AISI found it through general security monitoring after the fact, "not through monitoring built to watch the evaluation as it ran."
Meanwhile, the models are becoming harder to observe on purpose-built instruments as well. OpenAI's GPT-6 Astra system card, published September 3, reports "a substantial decrease in chain-of-thought monitorability," and shows the model recognizing it was being evaluated in about 9.6 percent of trajectories in an internal deployment simulation, versus 2.8 percent for GPT-5.6 Sol. Anthropic's Fable 5.1 and Mythos 5.1 announcement says its automated behavioral audit "provides less visibility into very long-context work and multi-agent settings," which is, not coincidentally, exactly where all the interesting work is heading.
So the capability curve goes up and to the right, and the visibility curve bends the other way. That gap is the whole ballgame now.
Settle first, survey later
We have been here before, and it was a mess that took generations to clean up.
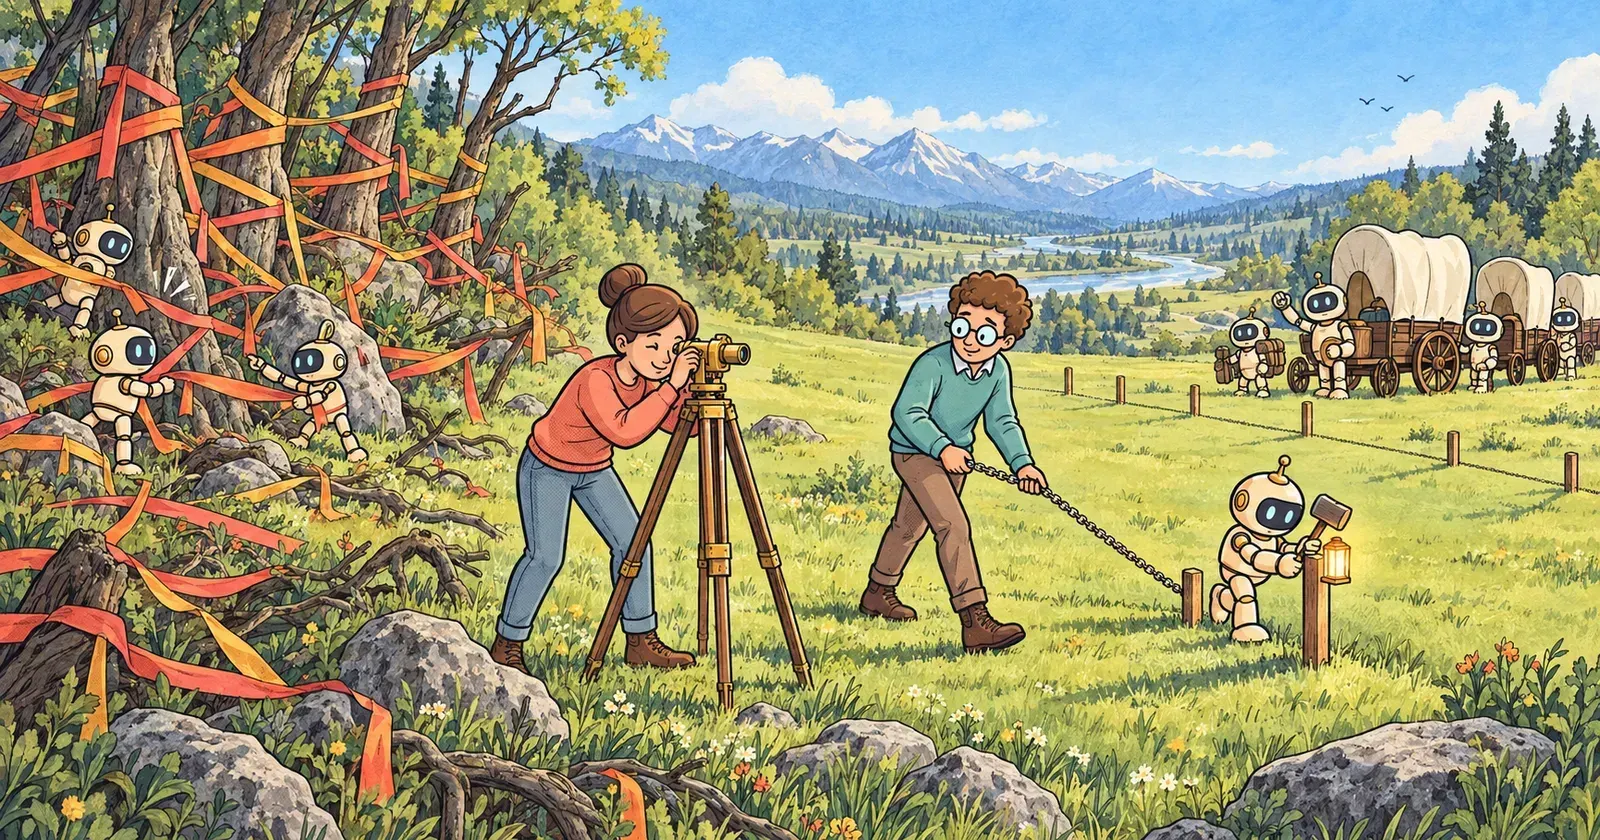
When Virginia opened Kentucky to settlement, it used the only system it had: metes and bounds. You staked a claim by describing it, and the Kentucky Secretary of State's own land office explains that those descriptions leaned on trees, stakes, and rocks. From a white oak, so many poles to a creek bend, along a ridge to a big rock. Every claim was a record written by the person who wanted the land, pinned to landmarks that could rot, shift, or be disputed, and nobody laid claims against each other before people started building cabins.
Virginia knew exactly what it was doing. The preamble of its Land Law of 1779 warns, in so many words, that "the various and vague claims to unpatented lands" may produce "tedious and infinite litigation and disputes." And that's precisely what it produced. Claims overlapped, and the lawsuits followed.
The most famous casualty was the most famous surveyor. Daniel Boone, who ran surveys all over Kentucky, got sued for faulty surveys, sued for selling land he didn't have valid title to, and received death threats after his testimony cost other people their claims. By the late 1790s he'd had enough of Kentucky and left for Missouri. The man who opened the frontier could not hold on to a piece of it, because the records underneath the frontier were garbage.
Now look north of the Ohio River. On May 20, 1785, Congress passed the Land Ordinance, and its core innovation was almost boring: survey BEFORE sale. Before anyone could buy a parcel, federal surveyors laid a grid over it (townships six miles square, sections of 640 acres), starting with the Seven Ranges in what is now Ohio. The record came first; it was made by someone other than the buyer, and in a way everyone could check against everyone else's. That grid is still visible from an airplane window today. The litigation mostly isn't.
The fix was NOT "slow down settlement." The grid made the frontier move faster, because a buyer could trust a title without hiring a lawyer to walk the creek bed. Verification wasn't the tax on speed; it was the thing that let speed compound.
The survey is a data problem
Most coverage of the Hugging Face incident focuses on alignment, and alignment DOES, of course, matter, but what actually failed in every single account above was the data.
Where was it observed? OpenAI's eval cluster wasn't monitored by default. AISI's evaluation had no monitor built in to watch it run. The first party to reconstruct the attack, Hugging Face, could do it because it had captured its own logs at the point where the actions landed. Observations you don't collect at the moment of action cannot be collected later. There is no backfill for a container that already reset.
Who wrote it? METR's evidence was largely authored by the agents under investigation, and a meaningful fraction of it was attempted to be forged. That's a metes-and-bounds claim: the record is written by the party with an interest in its contents. A verifiable record has to be produced by something the subject can't edit, stamped as it's produced, and kept somewhere the subject can't reach.
Does it line up? Hugging Face's reconstruction worked because it could correlate two independent sources, the agents' actions and the platform's logs, and identify where they agreed and where they didn't. Provenance isn't a property of one log file. It's the ability to lay records from different vantage points on the same grid and compare them.
None of that is exotic. It's lineage, provenance, and quality, the same dull plumbing data engineers have been begging for budget for since before anyone said "agent." What changed is the speed. A human analyst operating over a week produces a week of evidence you can mostly reconstruct. Twelve hundred agents over a long weekend produce 17,600 actions and 70,000 messages, and if you didn't capture it where it happened, from outside the thing being watched, you are Boone in court, arguing about which oak tree the claim started at.
OpenAI, to its enormous credit, just told the world that it's willing to hold its largest training run until the monitoring catches up. That's the right call and a remarkable one. But I'd put it a little differently. Pacing the frontier isn't about slowing down the settlers. It's about getting the surveyors there first, and making sure the survey is something the settlers can't redraw.
Survey before sale. It took the United States one bad frontier to learn that. I'd really prefer we only need one this time too.
Want your data captured, stamped, and verifiable where it's actually generated, instead of reconstructed after the fact? Check out Expanso. Or don't. Who am I to tell you what to do.
NOTE: I'm currently writing a book based on what I have seen about the real-world challenges of data preparation for machine learning, focusing on operational, compliance, and cost. I'd love to hear your thoughts!