LLMs Are Too Big. My Log Router Doesn't Need to Sing.
The model deciding whether to wake someone up doesn't need to sing Bohemian Rhapsody in Klingon. Working with Jev has me thinking about how much less we should ask of AI.
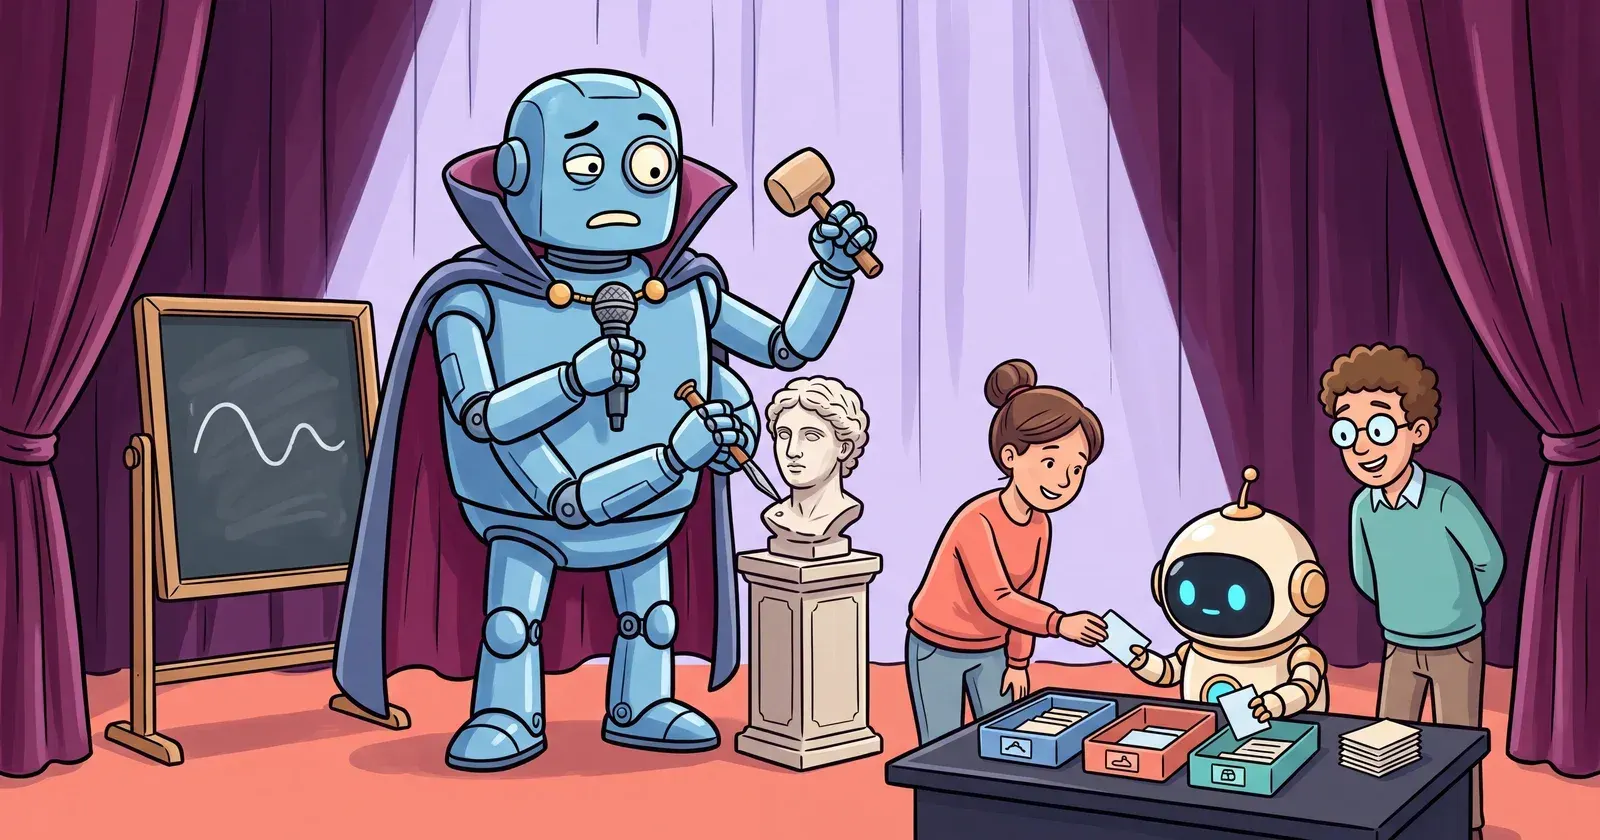
I think our language models are too big.
Which is a little bit spicy to say, because I don't actually mean the parameter count. I mean that we've gotten comfortable asking an incredibly general system to do a very specific job, and then doing a lot of work to keep it focused on that job.
Working on log routing with Expanso and Jev has made this feel a little ridiculous to me. The question we need answered is whether a particular event deserves someone's attention, especially when we already know the possible destinations and what should happen next. And yet the default approach in a lot of AI software is to bring in a model that can help with just about anything, explain the situation, and ask it to please stay inside the lines.
The capabilities you need to work on the Navier–Stokes equations are not necessarily the same ones you need to sing "Bohemian Rhapsody" in Klingon. Neither requires you to get all the angles right on Michelangelo's David. Having one system that can attempt all three is amazing. I use these tools, and I want them to keep getting better.
I don't think every piece of software needs access to that entire repertoire every time it makes a decision.
The job is smaller than the model
There is a lot of infrastructure work that sits in an awkward place. You can describe what you want fairly easily, but writing all the rules turns into a project of its own.
Take a log message that says config reload requested by unknown actor. It might have an INFO label, but that doesn't make it routine. You want something that can read the message and recognize why it could matter, without having to anticipate every way someone might phrase it.
Now suppose the same message keeps arriving. Once could deserve a look. Repeatedly, in a short window, could deserve something more urgent. The words haven't changed; the circumstances have.
That's the kind of judgment I want help with. I don't need a paragraph about the philosophy of incident response; I need a result the next piece of software can use, and I need to know what to do when the model isn't sure.
Jev, from TypeSafe, is interesting to me because it starts much closer to that requirement. You give it context and defined questions, and it returns typed judgments and probabilities: a choice among options, a score, or a yes/no probability. It doesn't provide an explanation and leaves you to figure out which part was the answer.
Of course, general LLMs can produce structured outputs too; we use that capability all the time. What interests me here is having a model built for these bounded decisions from the start, where there is less for the application to ask of it, and less for it to interpret afterward.
What we actually built
We put together an Expanso and Jev log-triage example that makes the division fairly concrete.
I've written up the implementation in our Expanso post on log triage with Jev. You can also watch the full walkthrough on Expanso's YouTube channel to see the routing and simulated outage in action.
Expanso handles the incoming records and the routing. Known routine events can go straight to archive using explicit checks, without asking a model anything, but for events that require judgment, the pipeline provides context, including how often a matching event has occurred within a 10-minute window.
Jev answers questions about whether the event is actionable, how severe it is, which team should own it, and whether the recurrence is concerning. The pipeline then applies its thresholds and sends the result toward page, notify, review, or archive.
I like that you can point to each part and say who is responsible for it. The model judges the event, the routing policy remains something we wrote and can inspect, and if a call can't be answered, Expanso holds it for retry and eventually sends it for review, while routine traffic continues.
There is a small detail in the demo that I think says a lot about this work. To count repeated events, you can normalize away numbers so that similar messages group together. But you absolutely cannot assume that the resulting group is safe to ignore. A successful health check and a failing one can look very similar once you've removed the status code and response time.
That is our responsibility as the people building the pipeline. A more capable model doesn't excuse us from deciding which information to preserve or which shortcuts are safe.
Fast enough to use everywhere
The part I find exciting is how often you could use this kind of judgment if the cost and latency were low enough.
You could ask about individual events as they move through a system, rather than collecting them in a pile, sending them somewhere else, and waiting for someone to interpret a summary. That changes which problems are worth tackling. A small decision that is too expensive to make a million times generally doesn't get made a million times.
TypeSafe currently lists Jev at $0.042 per million input tokens, with no charge for output tokens. Its own selected performance examples show subsecond responses. Those are vendor results, not a latency or throughput benchmark from our log-routing demo. Before putting this on a critical path, I'd still want to measure tail latency, sustained load, and the mistakes it makes on the actual data.
But at that price, with machine-usable answers returned quickly and cheaply enough that you can build them into ordinary software, this could be much more useful than another conversational interface for many of these jobs.
Typed output doesn't make the judgment correct; a wrong answer in perfectly valid JSON is still wrong. You need examples from your own environment, defensible thresholds, and a place for uncertain results to go. I would much rather build those controls around a limited question than ask a model to figure out the question, the policy, and the action all at once.
I expect more models like this
My bet is that we'll see more smaller, more targeted models alongside the big general ones. Jev is an early example of the direction I mean, although I am not making a claim about its undisclosed parameter count. TypeSafe also says customers use the same model weights; this isn't a separate fine-tune for each company.
The specialization is in what we ask the model to produce. There is plenty of room to get very good at turning messy text into a limited set of judgments that other machines can use. A log router, a support queue, and a data-quality check all have reasons to want that, even if none of them needs a chatbot.
Obviously, I have a stake in this through Expanso. We spend a lot of time thinking about what should happen to data as it moves, and these examples are part of that work. But the thing I keep coming back to is how much of the system we can already specify ourselves. We know where records should go. We know the policy. We mostly need help interpreting the messy bit in the middle.
I'd like to see us get more comfortable asking AI to do that smaller job well. There will be plenty of work left for the model that can discuss fluid dynamics and Klingon. I'm happy to keep using it for that. For the log router, I'd rather have the answer and get on with it.
Want to learn how intelligent data pipelines can reduce your AI costs? Check out Expanso. Or don't. Who am I to tell you what to do.*
NOTE: I'm currently writing a book based on what I have seen about the real-world challenges of data preparation for machine learning, focusing on operational, compliance, and cost. I'd love to hear your thoughts!